
About Me
My name is Handong Zhao. I am a Senior Research Scientist in Vision Language Lab (VLL) at Adobe Research in San Jose, CA. My research focuses on vision-language foundation models, multimodal agents, and post-training, with applications in visual understanding, generation, and tool-using creative AI systems. At Adobe, I have led and co-led research efforts on multimodal image editing agents, large-scale vision-language foundation models, and image/video generation post-training, with technologies transferred across Adobe Creative Cloud products.
I received my Ph.D. in Computer Engineering from the Department of Electrical and Computer Engineering at Northeastern University , Boston, MA. I was also a recipient of the National Science Foundation Innovation Corps (I-Corps™) award as an Entrepreneurial Lead.
Recent News
- [09/25] One NeurIPS-25 accepted on MLLM on Video Temporal Reasoning .
- [08/25] Two EMNLP papers accepted on GUI-Agent and TableQA.
- [06/25] Two VLM papers accepted. CVPR-25 on PhotoEye: image quality/aesthetic understanding and ICCV-25 on VSP: assessing spatial planning capability .
- [05/25] One LLM paper accepted by ACL-25 on Augmenting Generative Decoders with Representation Learning and Infilling Capabilities.
- [10/24] Appointed as ICLR-25 Area Chair.
- [09/24] One NeurIPS-24 and two EMNLP-24 papers accepted on VL representation learning and MLLM .
- [07/24] One ECCV-2024 accepted on Training-free Domain Generalization .
- [05/24] One TMLR journal accepted on Continual Graph Learning .
- [01/24] One ICLR-2024 accepted on Self-supervised Learning for Entity Segmentation .
- [09/23] One NeurIPS-2023 paper accepted on InfoPrompt for NLU .
- [07/23] One ICCV-2023 paper accepted on Spatial-Temporal Attention Controlled Diffusion Model .
- [05/23] One ACL-2023 finding paper accepted on " Domain Adaptation for Named Entity Recognition ".
- [03/23] One CVPR-2023 paper accepted on " Uncovering Disentaglement Capability of Diffusion Models ".
- [01/23] Appointed as Associate Editor for for IEEE TCSVT.
- [01/23] One ICLR-2023 paper accepted on " Continual Federated Learning ".
- [11/22] One AAAI-2023 paper accepted on " Compositional Image Retrieval ".
- [10/22] Two EMNLP-2022 papers accepted on " Multilingual Rep. Learning ".
- [08/22] Four CIKM-2022 papers accepted.
- [06/22] One RecSys-2022 on " Conversational Bundle Rec " accepted as oral.
- [06/22] Gave a talk on Federated Knowledge Composition in CVPR FedVision Workshop. [video recording]
- [05/22] One KDD-2022 on " KG Infusion for Tabular Pre-training Models " accepted.
- [04/22] One SIGIR-2022 on " Cross-domain Interaction Recommendation " accepted.
- [03/22] One CVPR-2022 on " Fashion CLIP " and one L4DC-2022 on " Neural Spatiotemporal Point Process " accepted.
- [02/22] Two ACL-2022 papers accepted on " Few-Shot Class-Incremental NER " and " Learning Adaptive Axis Attentions in Fine-tuning (Finding paper) ".
- [01/22] One paper " Neural Contextual Bandits with Deep Representation and Shallow Exploration " accepted by ICLR-2022 .
- [01/22] One paper on " Federated Learning for Multilingual NLU " accepted by WWW-2022 .
- [12/21] One paper on " Continual Federated Learning " accepted by ICLR-2023 .
- [12/21] One paper on " Cross-Domain Clustering " accepted by AAAI-2022 student abstract and poster program.
- [10/21] Two papers on " Continual NER " and " User-in-the-loop NER " accepted by NeurIPS ENLSP Workshop .
- [09/21] Two papers on " KD-based Graph Similarity Computation " and " Document Representation Learning " accepted by NeurIPS-2021 .
- [08/21] One short paper on " Sequential Recommender System " accepted by CIKM-2021 .
- [07/21] Two papers on " Source-Free DA " and " Semi-Supervised DA " accepted by ICCV-2021 .
- [05/21] One paper on " Explainable Column Annotation " accepted by KDD-2021 .
- [05/21] One paper on " KG-based Commonsense Reasoning " accepted by Findings of ACL-2021 .
- [04/21] I'm co-organizing The 3rd Workshop on Continual and Multimodal Learning for Internet of Things (CML-IOT) , at IJCAI-2021. The qualified papers are planned to invited as submissions to a journal special issue.
- [03/21] One CVPR-2021 on " Document Representation Learning " and one NAACL-2021 on " KG Enrichment " got accepted.
- [01/21] One ICLR-2021 on " Learning to Deceive KG " accepted.
- [12/20] One NeurIPS-KR2ML workshop paper on " KG-based Commonsense Reasoning " accepted.
- [11/20] One paper on " Learnable Subspace Clustering " accepted by TNNLS. [arXiv] .
- [09/20] One NeurIPS-2020 on " Self-Supervised Relationship Probing " accepted.
- [07/20] One ECCV-2020 on " Open Domain Image Manipulation " and one CIKM-2020 on " KG Reasoning for Recommendation " accepted.
- [06/20] One paper on " Linear Quadratic Regulator " accepted by ICML-2020 .
- [05/20] One paper on " Personalized Image Retrieval " accepted by KDD-2020 .
- [04/20] One survey paper on " Representation Learning for User Modeling " was accepted by IJCAI-2020 .
- [03/20] Our IJCAI-2020 tutorial " Robust Multi-view Visual Learning: A Knowledge Flow Perspective " was accepted (with prof. Zhengming Ding and prof. Ming Shao).
- [02/20] One paper on " Cross-domain Document Object Detection " was accepted by CVPR-2020 .
- [11/19] One SoCC-2019 poster and one BigData-2019 paper accepted.
- [09/19] I gave a talk on " Multi-modal Representation Learning ", invited by Prof. Hongfu Liu at Brandeis.
- [07/19] One ICCV-2019 paper got accepted. Congratulations to Jiuxiang.
- [04/19] Two KDD-2019 papers accepted on the topics of " Sequential Adversarial Learning " and " Interpretable User Modeling ".
- [02/19] My FIRST summer intern Jiuxiang's work on " Scene Graph Generation " got accepted by CVPR-2019 .
- [02/19] Co-host (with Myra and Subrata) session " AI For System " won Top Ten Session in Adobe-TechSummit-2019. Got my first trophy at Adobe.
- [12/18] Accepted the invitation to serve as PC member for IJCAI-2019 .
- [11/18] Will host a mini-summit, " Analyze, Predict, and Visualize: when RNNs meet Adobe ", at Adobe-TechSummit-2019 with Sungchul Kim.
- [10/18] I have one paper accepted by WSDM-2019 (Acceptance Rate: 16.4%).
- [10/18] AAAI-2019 Tutorial " Deep Multi-view Data Analytics " was accepted (with Allan Ding and Hongfu Liu).
- [05/18] Accepted the invitations to serve as PC for NIPS-2018 and SPC for AAAI-2019 .
- [03/18] One book proposal (with Allan and Prof. Raymond Fu) is accepted by Springer.
- [03/18] I accepted the invitation to serve as a member of the Program Committee for CVPR-2018 workshop on Analysis and Modeling of Faces and Gestures (AMFG).
- [02/18] I accepted the invitation to serve as a member of the Program Committee for ICMLA-2018.
- [01/18] I have one paper accepted by WACV-2018 .
Selected Publications
For the complete list of publications, please refer to my Google Scholar page.
* Project lead or primary advisor · † Equal advisor
-
 RetouchIQ: MLLM Agents for Instruction-Based Image Retouching with Generalist RewardTL;DR: Agent post-training for subjective creative tasks: introduces a generalist reward model with co-evolving policy–reward optimization to enable reinforcement learning for creative editing tasks that lack explicit, verifiable reward signals.CVPR 2026Paper Project Lead
-
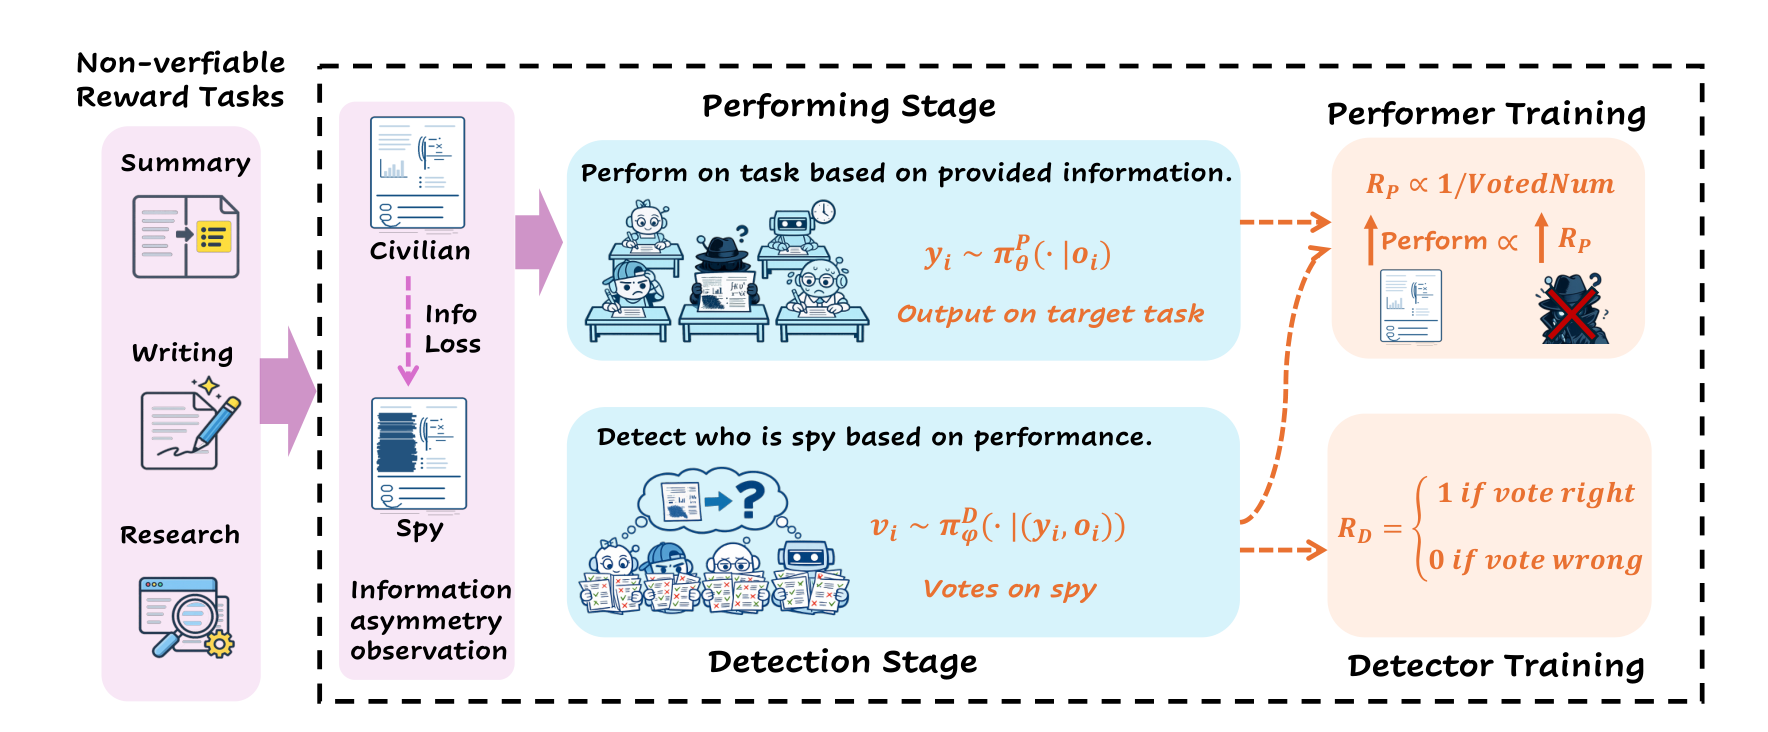 SpyRL: From RLVR to RLSVR — Task Transformation for Open-Ended LLM Self-ImprovementTL;DR: LLM post-training via self-improvement: transforms open-ended tasks into self-verifiable learning problems, enabling reinforcement learning without external reward models or LLM judges.COLM 2026
-
VividCam: Learning Unconventional Camera Motions from Virtual Synthetic VideosTL;DR: Scalable synthetic data for video generation: introduces a scalable synthetic data pipeline and a disentangled training recipe that isolates camera motion learning from low-quality synthetic appearances, enabling diverse and unconventional camera controls while preserving visual realism.ICML 2026
-
 VSP: Diagnosing the Dual Challenges of Perception and Reasoning in Spatial Planning Tasks for MLLMsTL;DR: Benchmarking visual-spatial planning: introduces a benchmark to systematically evaluate visual-spatial planning capabilities and reveal perception and reasoning limitations in multimodal LLMs.ICCV 2025 Co-Lead
-
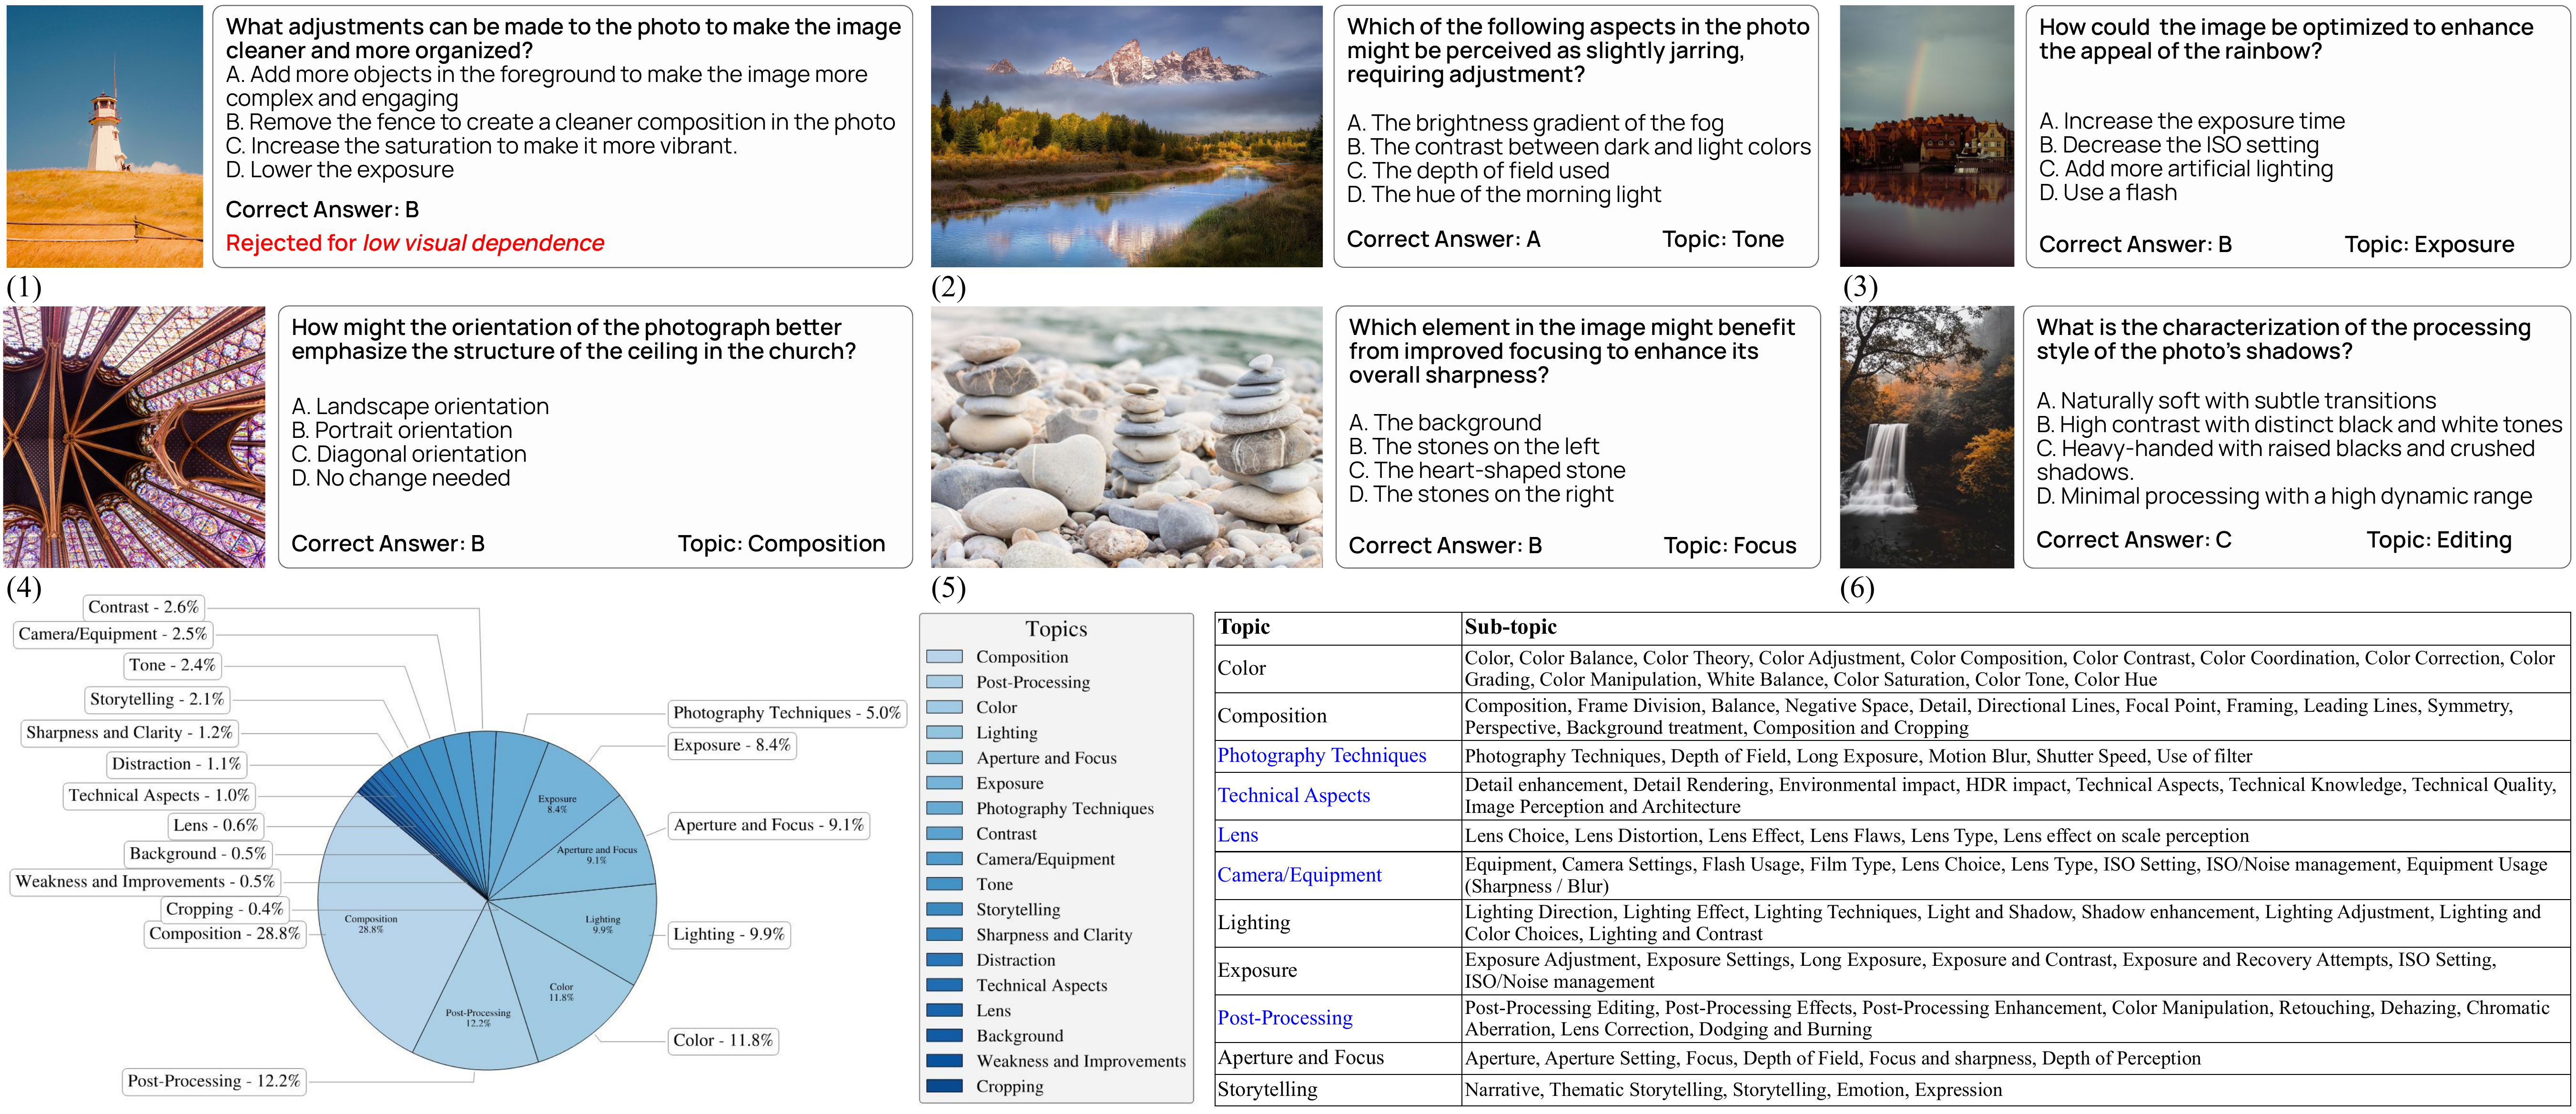 The Photographer’s Eye: Teaching Multimodal Large Language Models to See, and Critique Like PhotographersTL;DR: Foundation MLLM for photography and creative tasks: develops a photography-centric multimodal foundation model for understanding, evaluating, and reasoning about photographic aesthetics and creative decisions.CVPR 2025
Selected Talk

Keynote on CVPR FedVision Workshop
Federated Knowledge Composition
Handong Zhao
FedVision: International Workshop on Federated Learning for Computer Vision
New Orleans, Louisiana.
[
Recording
]